NEWS
AI Reasoning Models: How Modern AI Systems Are Learning to Think Through Complex Problems
Explore how AI reasoning models enhance problem-solving in AI systems.
Sudais Azlan
18 min read
AI Reasoning Models: How Modern AI Systems Are Learning to Think Through Complex Problems
AI & AI Research
What Are AI Reasoning Models?
AI reasoning models are a new generation of artificial intelligence systems designed to handle complex problems through deeper and more structured reasoning. Unlike traditional language models that often generate responses primarily by recognizing patterns learned during training, reasoning-focused models are designed to spend additional computational effort on understanding a problem, breaking it into smaller parts, exploring possible solutions, and reaching a more reliable conclusion.
This approach becomes particularly valuable when an AI system encounters problems that require multiple steps of logical thinking. Tasks involving mathematics, programming, scientific analysis, planning, and complex decision-making often require more than simply predicting the most likely sequence of words. Reasoning models attempt to address this challenge by analyzing relationships between different pieces of information, evaluating intermediate results, and refining their approach when necessary.
At their core, AI reasoning models aim to move artificial intelligence beyond simply generating plausible responses toward solving problems through more structured computational processes. They combine knowledge acquired during training with additional reasoning capabilities that help them determine how different pieces of information connect. This shift is contributing to the development of AI systems capable of tackling increasingly difficult problems with greater depth, flexibility, and reliability.
In simple terms: traditional AI can often recognize patterns and generate an answer, while reasoning models are designed to spend more effort working through a complex problem before reaching a conclusion.
AI & AI Research
How AI Reasoning Models Differ From Traditional Language Models
Traditional language models are primarily designed to predict and generate text based on patterns learned from large collections of training data. Given a prompt, these systems estimate which words or tokens are most likely to follow based on the relationships they have learned between different pieces of information. This approach has enabled modern language models to perform remarkably well across tasks such as writing, summarization, translation, question answering, and code generation.
However, predicting a highly plausible sequence of tokens is not always the same as solving a complex problem. Some tasks require an AI system to maintain multiple intermediate steps, compare alternative approaches, identify contradictions, and determine whether an intermediate result is logically consistent before producing a final answer. Reasoning models are designed to place greater emphasis on these problem-solving processes rather than relying only on immediate pattern recognition.
One of the most important differences is the amount of computational effort dedicated to solving a problem. A conventional language model may produce an answer directly after interpreting the prompt, while a reasoning-oriented system can allocate additional computation to analyze the problem, decompose it into smaller tasks, evaluate possible solutions, and improve its response before presenting the final result. This additional reasoning effort can be particularly useful for mathematical problems, programming tasks, scientific questions, and situations involving multiple constraints.
This does not mean that traditional language models are incapable of reasoning. Modern language models can already perform many forms of multi-step reasoning. The distinction is primarily about how the system is optimized and how much computational effort it is encouraged to use when facing difficult problems. Reasoning-focused architectures and training techniques aim to make this process more deliberate, reliable, and effective for challenging tasks.
In simple terms: a traditional language model is often optimized to generate the most appropriate response from learned patterns, while a reasoning model is designed to spend additional computational effort working through the problem before producing its final answer.
AI & AI Research
How Do AI Reasoning Models Work?
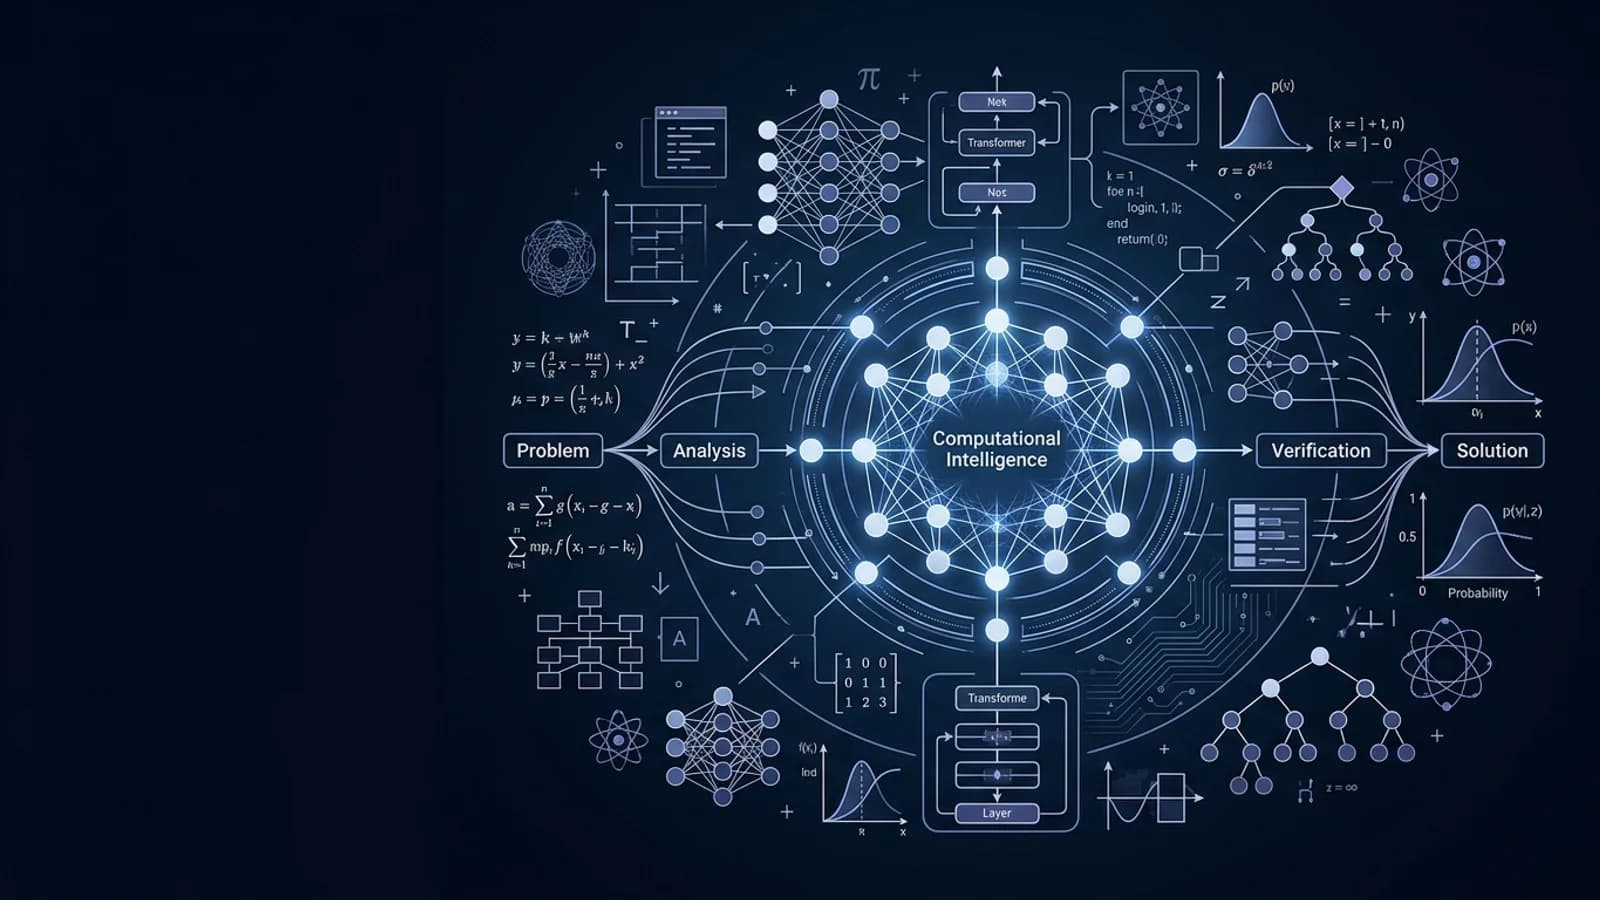
AI reasoning models work by allocating additional computational effort to problems that require multiple steps of analysis. Instead of immediately generating a final response, a reasoning-oriented system can first interpret the problem, identify the information that is relevant, break the task into smaller components, and determine which steps are necessary to reach a reliable solution. This process allows the model to approach difficult problems in a more structured way.
A key part of this process is problem decomposition. Complex questions are often difficult because they contain several interconnected requirements. By separating a problem into smaller subproblems, an AI system can focus on one part at a time and then combine the results. For example, a programming problem may require understanding the requirements, identifying the algorithm, considering edge cases, writing the implementation, and checking whether the resulting solution satisfies the original requirements.
Reasoning models can also evaluate intermediate results rather than treating the first generated solution as automatically correct. When solving a difficult task, the system may compare different possible approaches, identify inconsistencies, reconsider previous assumptions, and refine its solution. This additional computation can improve performance on tasks where a small mistake in an early step could cause the final answer to become incorrect.
The underlying process depends on the model architecture, training methods, inference strategies, and computational resources available to the system. Modern AI research is exploring different techniques for encouraging models to reason more effectively, including specialized training, reinforcement learning, additional inference-time computation, tool usage, verification, and methods for evaluating intermediate solutions. These techniques are helping researchers develop systems that can handle increasingly complex reasoning tasks.
In simple terms: an AI reasoning model can approach a difficult problem like a structured problem-solving process: understand the task, break it into smaller steps, work through those steps, evaluate the results, and then produce the final answer.
AI & AI Research
Key Components of AI Reasoning
The ability of an AI system to reason through difficult problems does not come from a single technique. It is the result of multiple capabilities working together during training and inference. These capabilities allow a model to understand the problem, organize relevant information, explore possible solutions, evaluate intermediate results, and produce a final response that is more consistent with the requirements of the task.
Understanding these components is important because reasoning is more than simply generating a longer response. A capable reasoning system must be able to maintain relationships between different pieces of information, follow logical dependencies, recognize when an approach is not working, and allocate additional computation when a problem requires deeper analysis.
| Component | Purpose | Example |
|---|---|---|
| Problem Understanding | Identifies the actual objective, constraints, and relevant information within a problem. | Determining what a programming problem is actually asking before selecting an algorithm. |
| Problem Decomposition | Breaks a complex task into smaller and more manageable subproblems. | Separating a mathematical problem into several intermediate calculations. |
| Logical Inference | Establishes relationships between known information and possible conclusions. | Using known conditions to determine which conclusion logically follows. |
| Intermediate Evaluation | Checks whether intermediate results are consistent with the problem and previous steps. | Detecting an incorrect calculation before it affects the final result. |
| Solution Refinement | Revises an approach when the current solution is incomplete, inconsistent, or inefficient. | Trying an alternative algorithm when the first approach fails to satisfy the requirements. |
| Verification | Evaluates the final solution against the original problem and its constraints. | Testing generated code against expected inputs and edge cases. |
These components are closely connected rather than operating as completely independent stages. A reasoning model may move between them as it works through a difficult task. For example, discovering an inconsistency during verification may cause the system to return to an earlier step, reconsider its assumptions, and generate a different solution. This iterative behavior is one of the important characteristics of advanced reasoning systems.
Reasoning Workflow
Understand
Identify the problem
Decompose
Break it into steps
Reason
Explore solutions
Verify
Check the result
Answer
Produce the result
The practical value of these components becomes especially clear when AI systems are applied to tasks where correctness matters more than simply producing fluent text. Mathematical reasoning, software development, scientific research, data analysis, planning, and complex decision-making can all benefit from systems that are capable of spending additional computational effort on difficult problems.
Key takeaway: AI reasoning is best understood as a combination of problem understanding, decomposition, inference, evaluation, refinement, and verification. The stronger these capabilities become, the better an AI system can handle problems that require multiple connected steps rather than simple pattern matching.
AI & AI Research
How Are AI Reasoning Models Trained?
Training AI reasoning models involves more than teaching a system to recognize patterns and generate natural language. The objective is to develop models that can solve problems through structured and multi-step processes. To achieve this, researchers combine large-scale pretraining with specialized training techniques that encourage models to perform better on tasks requiring logical reasoning, mathematical problem-solving, programming, planning, and complex decision-making.
The process typically begins with pretraining on large and diverse datasets. During this stage, the model learns relationships between tokens, concepts, facts, language structures, code, and other forms of information. Although pretraining is not specifically designed to create a reasoning model, it provides the foundational knowledge and capabilities that the system can later use when solving more difficult problems.
After pretraining, researchers can apply additional training methods that focus more directly on reasoning performance. These methods may expose the model to problems paired with solutions, demonstrations of effective problem-solving strategies, or feedback that rewards better outcomes. The goal is not simply to make the model produce longer answers, but to improve its ability to identify useful intermediate steps and arrive at more reliable solutions.
| Training Stage | Main Objective | Contribution to Reasoning |
|---|---|---|
| Pretraining | Learn broad patterns, knowledge, language, code, and relationships from large datasets. | Provides the foundational knowledge required for solving problems. |
| Supervised Fine-Tuning | Adapt the model using carefully prepared examples and desired responses. | Helps the model learn effective response and problem-solving patterns. |
| Reasoning-Oriented Training | Focus training on tasks that require multiple connected reasoning steps. | Improves performance on mathematical, programming, analytical, and logical problems. |
| Reinforcement Learning | Uses feedback or reward signals to encourage more effective behaviors. | Can encourage strategies that produce more accurate and useful solutions. |
| Evaluation | Measure performance across difficult and diverse reasoning tasks. | Identifies weaknesses and helps researchers improve future model versions. |
One important development in modern AI research is the use of additional computation during inference. Instead of relying entirely on the amount of computation used during training, a reasoning model can be designed to use more computational resources when it encounters a difficult problem. This creates a distinction between improving the model itself and allowing the model to spend more time or computation solving a particular task.
Reinforcement learning can also play an important role in developing reasoning capabilities. In this setting, the model receives feedback based on the quality or correctness of its output. Over many training examples, the system can learn which behaviors tend to produce better results. Depending on the training approach, the reward signal may focus on the final answer, the usefulness of the solution, or other measurable properties of the task.
From Training to Reasoning
1
Learn broad knowledge
The model develops a general understanding of language, concepts, code, and information during large-scale pretraining.
2
Learn problem-solving patterns
Specialized training exposes the system to tasks that require structured analysis and multi-step solutions.
3
Optimize reasoning behavior
Additional optimization techniques can encourage strategies that lead to more reliable solutions.
4
Evaluate difficult tasks
The resulting system is tested against increasingly challenging reasoning benchmarks and real-world problems.
Training therefore provides the foundation for an AI reasoning system, but it is only one part of the overall process. The behavior observed when the model is solving a problem also depends on inference-time computation, prompting, available tools, verification mechanisms, and the design of the surrounding AI system. This combination of training and inference is a major area of ongoing research in modern artificial intelligence.
Key takeaway: AI reasoning models are developed by combining broad knowledge learned during pretraining with specialized optimization and reasoning-focused techniques. The result is a system that can use its learned knowledge together with additional computation to tackle problems requiring deeper analysis.
AI & AI Research
Inference-Time Compute: Why More Thinking Can Improve AI Performance
One of the most important ideas behind modern AI reasoning models is inference-time computation. Traditional AI systems often perform most of their computational work during training and then generate an answer relatively quickly when they receive a prompt. Reasoning-oriented systems introduce a different approach: they can allocate additional computation while solving a difficult problem, allowing the model to explore, evaluate, and refine possible solutions before producing its final response.
This distinction is important because model intelligence is not determined exclusively by the number of parameters or the amount of data used during training. For certain tasks, performance can also improve when a model is given more computational resources at inference time. Instead of treating every question as equally difficult, an AI system can devote relatively little computation to simple requests and substantially more computation to problems that require deeper analysis.
Core Concept
Training Compute vs. Inference Compute
Training determines what capabilities a model can learn, while inference determines how much computation the model can use when applying those capabilities to a particular problem.
More difficult problem
↑ Compute
| Aspect | Training | Inference |
|---|---|---|
| Primary Purpose | Learn knowledge, patterns, representations, and capabilities. | Apply learned capabilities to solve a particular task. |
| When It Happens | Before the model is deployed for normal usage. | Every time the deployed model receives a new request. |
| Computational Role | Builds the capabilities that the model can later use. | Determines how much computational effort can be spent solving the current problem. |
| Reasoning Impact | Teaches the model useful reasoning behaviors and capabilities. | Gives the model an opportunity to apply additional computation to difficult problems. |
Why Inference-Time Compute Matters
Consider two problems presented to the same AI system. The first may be a simple factual question that can be answered almost immediately. The second may require several mathematical operations, logical constraints, and verification steps. Treating both problems with exactly the same amount of computational effort can be inefficient. A reasoning-oriented system can instead adapt its computational effort to the complexity of the task.
This creates an important trade-off between quality, latency, and cost. More inference-time computation can potentially improve the quality of a solution, but it can also require more processing time and computational resources. For production AI systems, engineers therefore need to determine when deeper reasoning is valuable enough to justify the additional cost.
Simple Task
Low Compute
Straightforward requests can often be handled with relatively little additional reasoning.
Complex Task
Higher Compute
Multi-step problems can benefit from additional analysis and solution exploration.
Production System
Adaptive Compute
Systems can balance reasoning depth against latency, cost, and reliability requirements.
The Quality–Cost–Latency Trade-Off
Increasing reasoning effort does not automatically guarantee a correct answer. Additional computation can provide more opportunities to analyze a problem, but the underlying model can still make incorrect assumptions, misunderstand information, or generate an invalid solution. As a result, reasoning systems must be evaluated carefully rather than assuming that longer computation always produces better intelligence.
Quality
More reasoning can improve performance on difficult tasks when the additional computation is used effectively.
Latency
Deeper reasoning may increase the time required before the user receives the final response.
Cost
Additional inference computation can increase infrastructure and operational costs at scale.
For AI engineers, this means that reasoning should be treated as a resource that can be managed rather than simply maximized. A well-designed AI application may use fast generation for routine requests while reserving deeper reasoning, verification, retrieval, or tool use for tasks where accuracy and reliability are more important than response speed.
Key takeaway: inference-time compute allows AI reasoning models to spend additional computational effort on difficult problems. This can improve performance on complex tasks, but production systems must balance reasoning depth with accuracy, latency, and computational cost.
AI & AI Research
How Chain-of-Thought and Reinforcement Learning Improve AI Reasoning
The development of modern AI reasoning systems has been strongly influenced by research into how large language models can solve problems through intermediate reasoning steps. Two important ideas in this area are chain-of-thought reasoning and reinforcement learning. Together with large-scale pretraining and inference-time computation, these approaches have helped researchers investigate how language models can become more capable at solving complex mathematical, logical, programming, and scientific problems.
Chain-of-thought refers to a problem-solving approach in which a model generates or internally uses a sequence of intermediate reasoning steps before arriving at a final answer. Instead of attempting to map a complex question directly to a conclusion, the model can break the problem into smaller operations. This can be particularly useful when the correct answer depends on several connected deductions or calculations.
Research Insight
Complex reasoning tasks can benefit when language models are encouraged to work through intermediate steps instead of producing only an immediate final answer.
This idea became especially influential through research on chain-of-thought prompting and subsequent work on reasoning-oriented training.
Chain-of-Thought Reasoning
In a typical multi-step reasoning task, an AI system may need to establish several intermediate relationships before it can determine the final solution. Chain-of-thought techniques encourage the model to represent these intermediate steps rather than jumping directly to the conclusion. Research has shown that sufficiently capable language models can benefit from this approach on certain reasoning benchmarks.
For example, a mathematical problem may require identifying the relevant variables, selecting an appropriate equation, performing several calculations, and checking the resulting value. If the model attempts to produce the final answer immediately, an error in any implicit step can remain undetected. Structured intermediate reasoning can make the solution process more systematic.
| Approach | Process | Typical Advantage | Main Limitation |
|---|---|---|---|
| Direct Generation | Produces an answer directly from the input. | Fast and computationally efficient for straightforward tasks. | More vulnerable to errors on complex multi-step problems. |
| Chain-of-Thought | Uses intermediate reasoning steps before producing a conclusion. | Can improve performance on certain mathematical and logical tasks. | Intermediate reasoning is not guaranteed to be correct. |
| Reinforcement Learning | Optimizes model behavior using reward or feedback signals. | Can encourage strategies that lead to stronger task performance. | Requires carefully designed objectives and reliable evaluation. |
| Inference-Time Scaling | Allocates additional computation while solving difficult tasks. | Allows greater computational effort to be applied when needed. | Can increase latency and computational cost. |
Reinforcement Learning for Reasoning
Reinforcement learning provides another mechanism for improving reasoning behavior. Instead of relying only on examples that demonstrate what an answer should look like, reinforcement learning can optimize a model using feedback about the quality of its behavior or final outcome. In reasoning tasks, the reward can be connected to measurable properties such as correctness, successful task completion, or adherence to a defined objective.
This creates an important distinction between learning an answer and learning how to solve a class of problems. When the training objective rewards successful problem solving, the model can discover strategies that are useful across many different examples. This is one reason reinforcement-learning-based approaches have become an important research direction for advanced reasoning models.
Reasoning Optimization Loop
1
Problem
The model receives a task that requires reasoning or structured problem solving.
↓
2
Candidate Reasoning
The system explores one or more possible approaches to solving the task.
↓
3
Evaluation
The result is assessed using a reward signal, verifier, or measurable success criterion.
↓
4
Optimization
Training updates encourage behaviors associated with stronger outcomes.
Why Verification Matters
More reasoning does not automatically mean correct reasoning. A model can generate a long and convincing sequence of intermediate steps while still reaching an incorrect conclusion. This makes verification an important component of reliable reasoning systems.
Verification can take different forms depending on the task. Mathematical solutions can be checked against known constraints or computational procedures. Generated code can be executed against tests. Scientific responses can be compared against retrieved evidence. Planning systems can evaluate whether proposed actions satisfy their constraints. These verification mechanisms help separate plausible reasoning from reasoning that actually produces a valid result.
Important distinction: a reasoning trace can look convincing without being logically correct. Reliable AI systems therefore need evaluation and verification mechanisms in addition to stronger reasoning capabilities.
Research References
The development of AI reasoning is supported by a growing body of research in language modeling, prompting, reinforcement learning, and inference-time computation. The following papers provide useful technical foundations for understanding how these capabilities have evolved.
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Wei et al. — Research on how intermediate reasoning steps can improve the performance of sufficiently capable language models on complex reasoning tasks.
arXiv Research Paper →
Self-Consistency Improves Chain of Thought Reasoning in Language Models
Wang et al. — Introduces an approach that samples multiple reasoning paths and selects a more consistent answer rather than relying on a single reasoning path.
arXiv Research Paper →
Training Language Models to Follow Instructions with Human Feedback
Ouyang et al. — A foundational study of reinforcement learning from human feedback for aligning language models with desired behavior.
arXiv Research Paper →
Let's Verify Step by Step
Lightman et al. — Research investigating process-level supervision and verification for improving mathematical reasoning.
arXiv Research Paper →
Together, these research directions illustrate an important shift in AI development. Progress is increasingly focused not only on making models larger or giving them more training data, but also on improving how they allocate computation, construct solutions, evaluate intermediate results, and learn from feedback. This broader perspective is central to the development of increasingly capable AI reasoning systems.
Key takeaway: chain-of-thought methods, reinforcement learning, inference-time computation, and verification represent complementary approaches to improving AI reasoning. Modern reasoning systems increasingly combine these ideas to solve problems that demand deeper analysis rather than simple pattern-based generation.